Structured data has usually been sold to marketing teams as a technical SEO task: add the right JSON-LD, validate it, and hope Google rewards the page with a richer search result. A new Search Engine Land briefing for an upcoming SMX Now session points to a more consequential use case. The question is no longer only whether a page’s schema is valid, but whether Google’s language systems actually recognize the same entities, relationships and areas of expertise that the brand claims for itself.
The session, scheduled for September 16, 2026, features Ray Martinez, VP of SEO at Archer Education, and focuses on measuring the gap between entities declared in Schema.org markup and entities identified by Google’s natural language processing tools. According to Search Engine Land, the workflow uses schema markup, the Google Cloud Natural Language API and agentic coding tools to turn existing structured data into a queryable knowledge graph, then compare it with competitor content and NLP output.
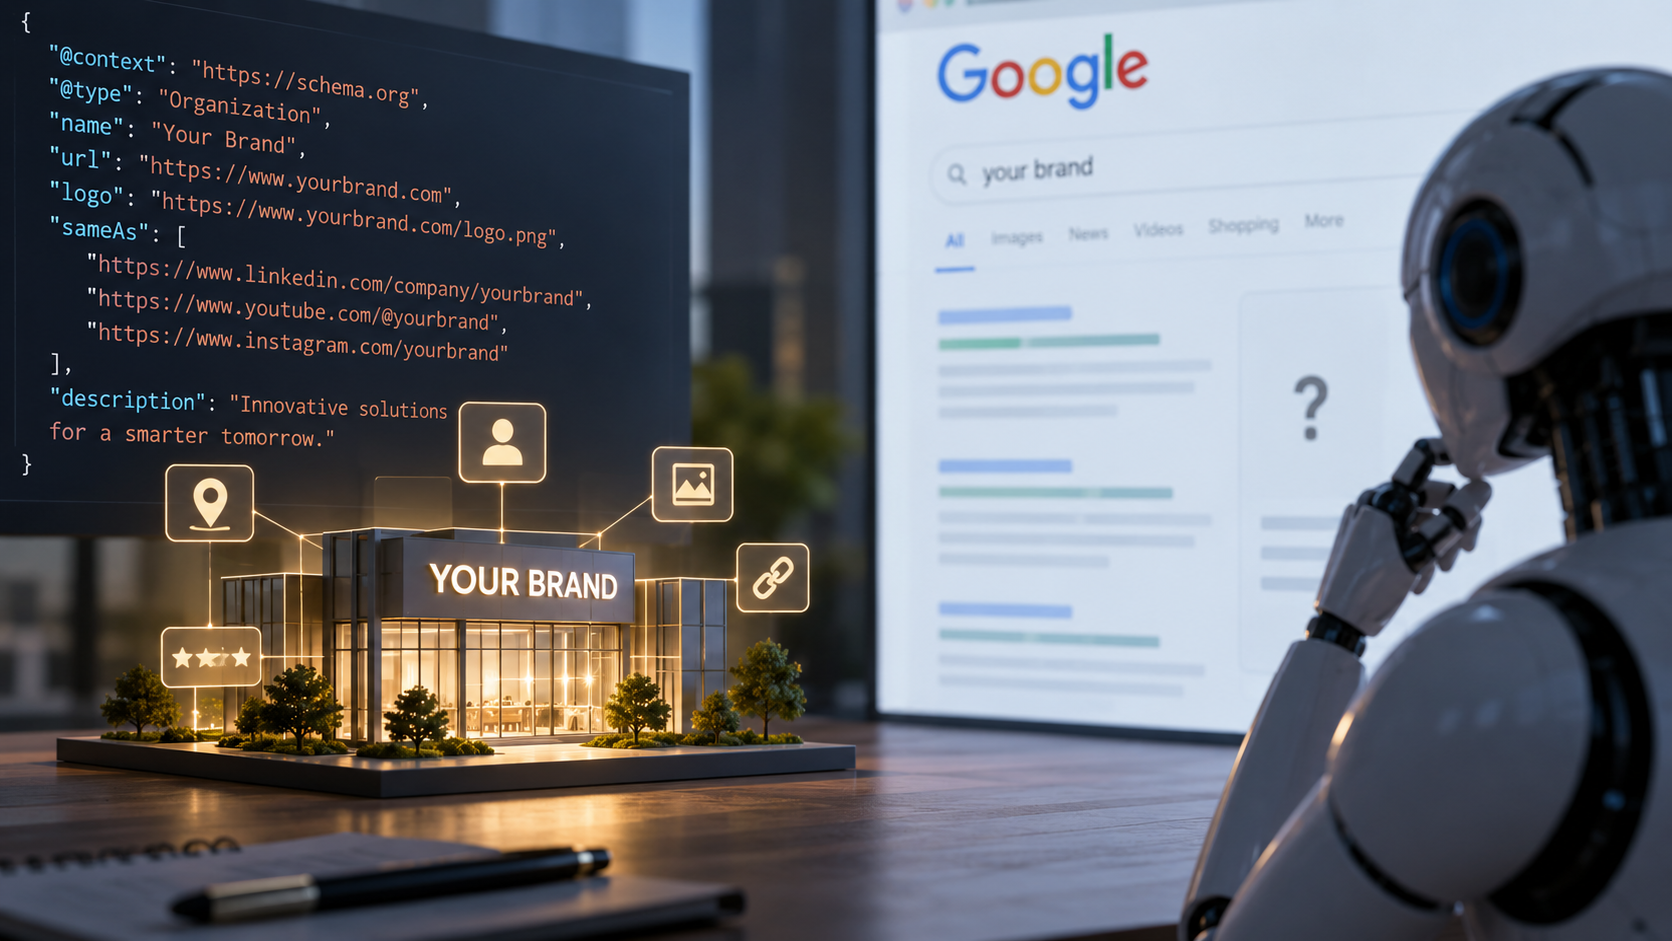
That framing matters because it quietly changes the purpose of schema. Instead of treating markup as a one-way instruction to a search engine, it treats markup as a hypothesis about brand identity. The brand says, in machine-readable form, what it is, what it sells, which topics matter, who its authors are, what products or services it owns and how those objects connect. The audit then asks whether the rest of the web page, the site architecture and the surrounding evidence make that hypothesis believable to machines.
Valid markup is not the same as recognized meaning
Google’s own documentation describes structured data as a standardized way to provide explicit clues about the meaning of a page and classify its content. It also says most Google Search structured data uses the Schema.org vocabulary, while Google Search Central remains the definitive reference for how structured data behaves in Google Search. In practical terms, schema can help Google understand page content and power supported rich-result features, but it is not a mechanism for forcing Google to accept a brand’s preferred interpretation.
That distinction is becoming more important as search interfaces shift from lists of links toward generated answers, summaries and recommendations. A brand may define itself as a specialist in a valuable topic, but if its pages describe that topic vaguely, fail to connect related pages, or omit the entities that buyers and competitors consistently use, machine systems may build a weaker model of the brand than the marketing team expects. The markup can be syntactically correct while the brand remains semantically underdeveloped.
The Google Cloud Natural Language API illustrates why this gap is measurable. Its entity model can return a representative entity name, entity type, metadata, mentions and a salience score indicating how central an entity is to a document. That does not reveal the full internal machinery of Google Search, and it should not be treated as a direct ranking oracle. But it gives SEO and content teams a practical proxy for asking a useful question: when a machine reads this page, what does it actually think the page is about?
The overlooked problem is entity mismatch
Traditional structured-data audits tend to look for missing required fields, implementation errors, unsupported types or eligibility problems in Google’s rich result tools. Those checks are still necessary. They help teams avoid invalid, incomplete or inaccurate markup and keep structured data aligned with Google’s documented requirements. But they rarely answer a deeper strategic question: are the entities declared in schema reinforced by the visible content that users and crawlers actually see?
An entity mismatch can take several forms. A company may use Organization schema with useful sameAs references, but the page copy may fail to mention the industries, products, integrations or use cases that should make the brand distinctive. A product page may mark up a product correctly, while the surrounding text leaves important technical attributes, buyer problems or comparison criteria implicit. A publisher may mark up authors and articles, yet leave expertise signals scattered across biography pages, topic hubs and internal links that do not clearly connect.
The result is a brand that has labels but weak associations. That matters for ordinary search, where Google needs to understand relevance, and it matters even more for AI-mediated discovery, where retrieval systems need sources that can be summarized, attributed and connected to a user’s specific question. In that environment, the winner is not always the site with the longest page or the most elaborate schema block. It may be the site whose entities and relationships are easiest for machines to retrieve with confidence.
Competitors may be teaching machines a clearer story
The competitive layer of the Search Engine Land workflow is especially important. Ranking audits often compare titles, links, page speed, content length and keyword coverage. Entity audits compare the shape of meaning. A rival may be easier to surface not because it uses a magical schema type, but because it consistently connects its brand to named problems, buyer roles, regulatory contexts, product categories, locations, partners and case studies across multiple pages.
That kind of consistency can become a retrieval advantage. If two companies serve the same market, but one repeatedly links its services to recognizable entities and the other relies on broad positioning language, machine systems may develop a much sharper picture of the first company. Schema can declare the intended identity, but the surrounding site has to provide corroborating evidence. Competitor analysis can reveal which entities are missing, which are present but not salient, and which relationships are better expressed elsewhere in the market.
This is where agentic tooling becomes useful, provided teams treat it as a workflow accelerator rather than a source of truth. An agent can extract schema, map declared entities, run page text through NLP tools, compare competitor pages and produce a list of gaps. Humans still need to decide which gaps matter commercially, which claims are supportable, and which content changes would improve user understanding rather than merely stuffing entity names into copy.
Schema is becoming part of brand infrastructure
The broader shift is that schema is starting to look less like a search feature and more like part of a brand’s information architecture. A clean knowledge graph can help a company keep its products, people, locations, articles, videos and authority signals consistent across a site. But a graph that exists only in JSON-LD, disconnected from page content and internal linking, is fragile. It may pass a validator while failing to persuade the systems that actually interpret language.
Recent research on retrieval systems points in the same direction. A 2026 paper on structured linked data for agent-orchestrated retrieval found that JSON-LD alone produced only modest improvements in its experimental setup, while richer entity pages and navigational affordances produced larger gains in retrieval accuracy and answer quality. The study does not prove that every commercial website will see the same result, but it supports a practical lesson: structured data is more powerful when it is part of a broader, navigable semantic layer rather than an isolated markup block.
For SEO teams, the next audit checklist should therefore include three questions. What does the schema say the brand is? What do NLP systems recognize from the visible page and connected site content? What do competitors make clearer than we do? The answer may lead to schema refinements, but it may also lead to new explanatory pages, better internal links, clearer definitions, stronger author profiles, improved product information or more precise case studies.
The risk is that marketers misread this trend as another optimization trick for AI search. The better interpretation is more demanding. Brands need to make their real expertise explicit, consistent and verifiable across the material that humans read and machines parse. Schema can define the desired map. The hard work is making sure the terrain matches it.